Mothership
AI
Apps call models by fixed tiers (fast, smart, deep, embedding-default). Only the gateway holds provider keys, and usage is recorded per app, company and person.
Tiers
Apps ask for a tier rather than a model name, so app code runs unchanged on any Mothership. The names are Galpi's.
| Tier | For |
|---|---|
fast |
Cheap classification and transforms. Falls back to smart |
smart |
Balanced; used when no tier is given |
deep |
Quality first. Falls back to smart |
embedding-default |
Embeddings (re-ranking in knowledge search) |
Any other name is validation_failed; a tier without a model is ai_profile_unconfigured. An exact model can be pinned when it is allowlisted (MOTHERSHIP_AI_ALLOWED_MODELS), otherwise ai_model_not_allowed.
The service's provider
Any OpenAI-compatible server works (OpenAI, vLLM, Ollama, LiteLLM …).
MOTHERSHIP_AI_API_KEY=sk-...             # required to switch it on; any value for servers that ignore keys
MOTHERSHIP_AI_BASE_URL=                  # empty: api.openai.com, otherwise …/v1
MOTHERSHIP_AI_MODEL_FAST=gpt-4.1-nano
MOTHERSHIP_AI_MODEL_SMART=gpt-4.1-mini   # one model is enough to start
MOTHERSHIP_AI_MODEL_DEEP=gpt-4.1
MOTHERSHIP_AI_MODEL_EMBEDDING=text-embedding-3-small
MOTHERSHIP_AI_MAX_OUTPUT_TOKENS=4096     # hard cap per request
MOTHERSHIP_AI_TIMEOUT_SECONDS=60
MOTHERSHIP_AI_STREAM_MAX_SECONDS=300
Galpi's names (LLM_BASE_URL, LLM_API_KEY, LLM_MODEL, MODE_FAST_MODEL …) are read too when LLM_API_FORMAT=openai. MOTHERSHIP_AI_* wins when both are set.
A company's own provider
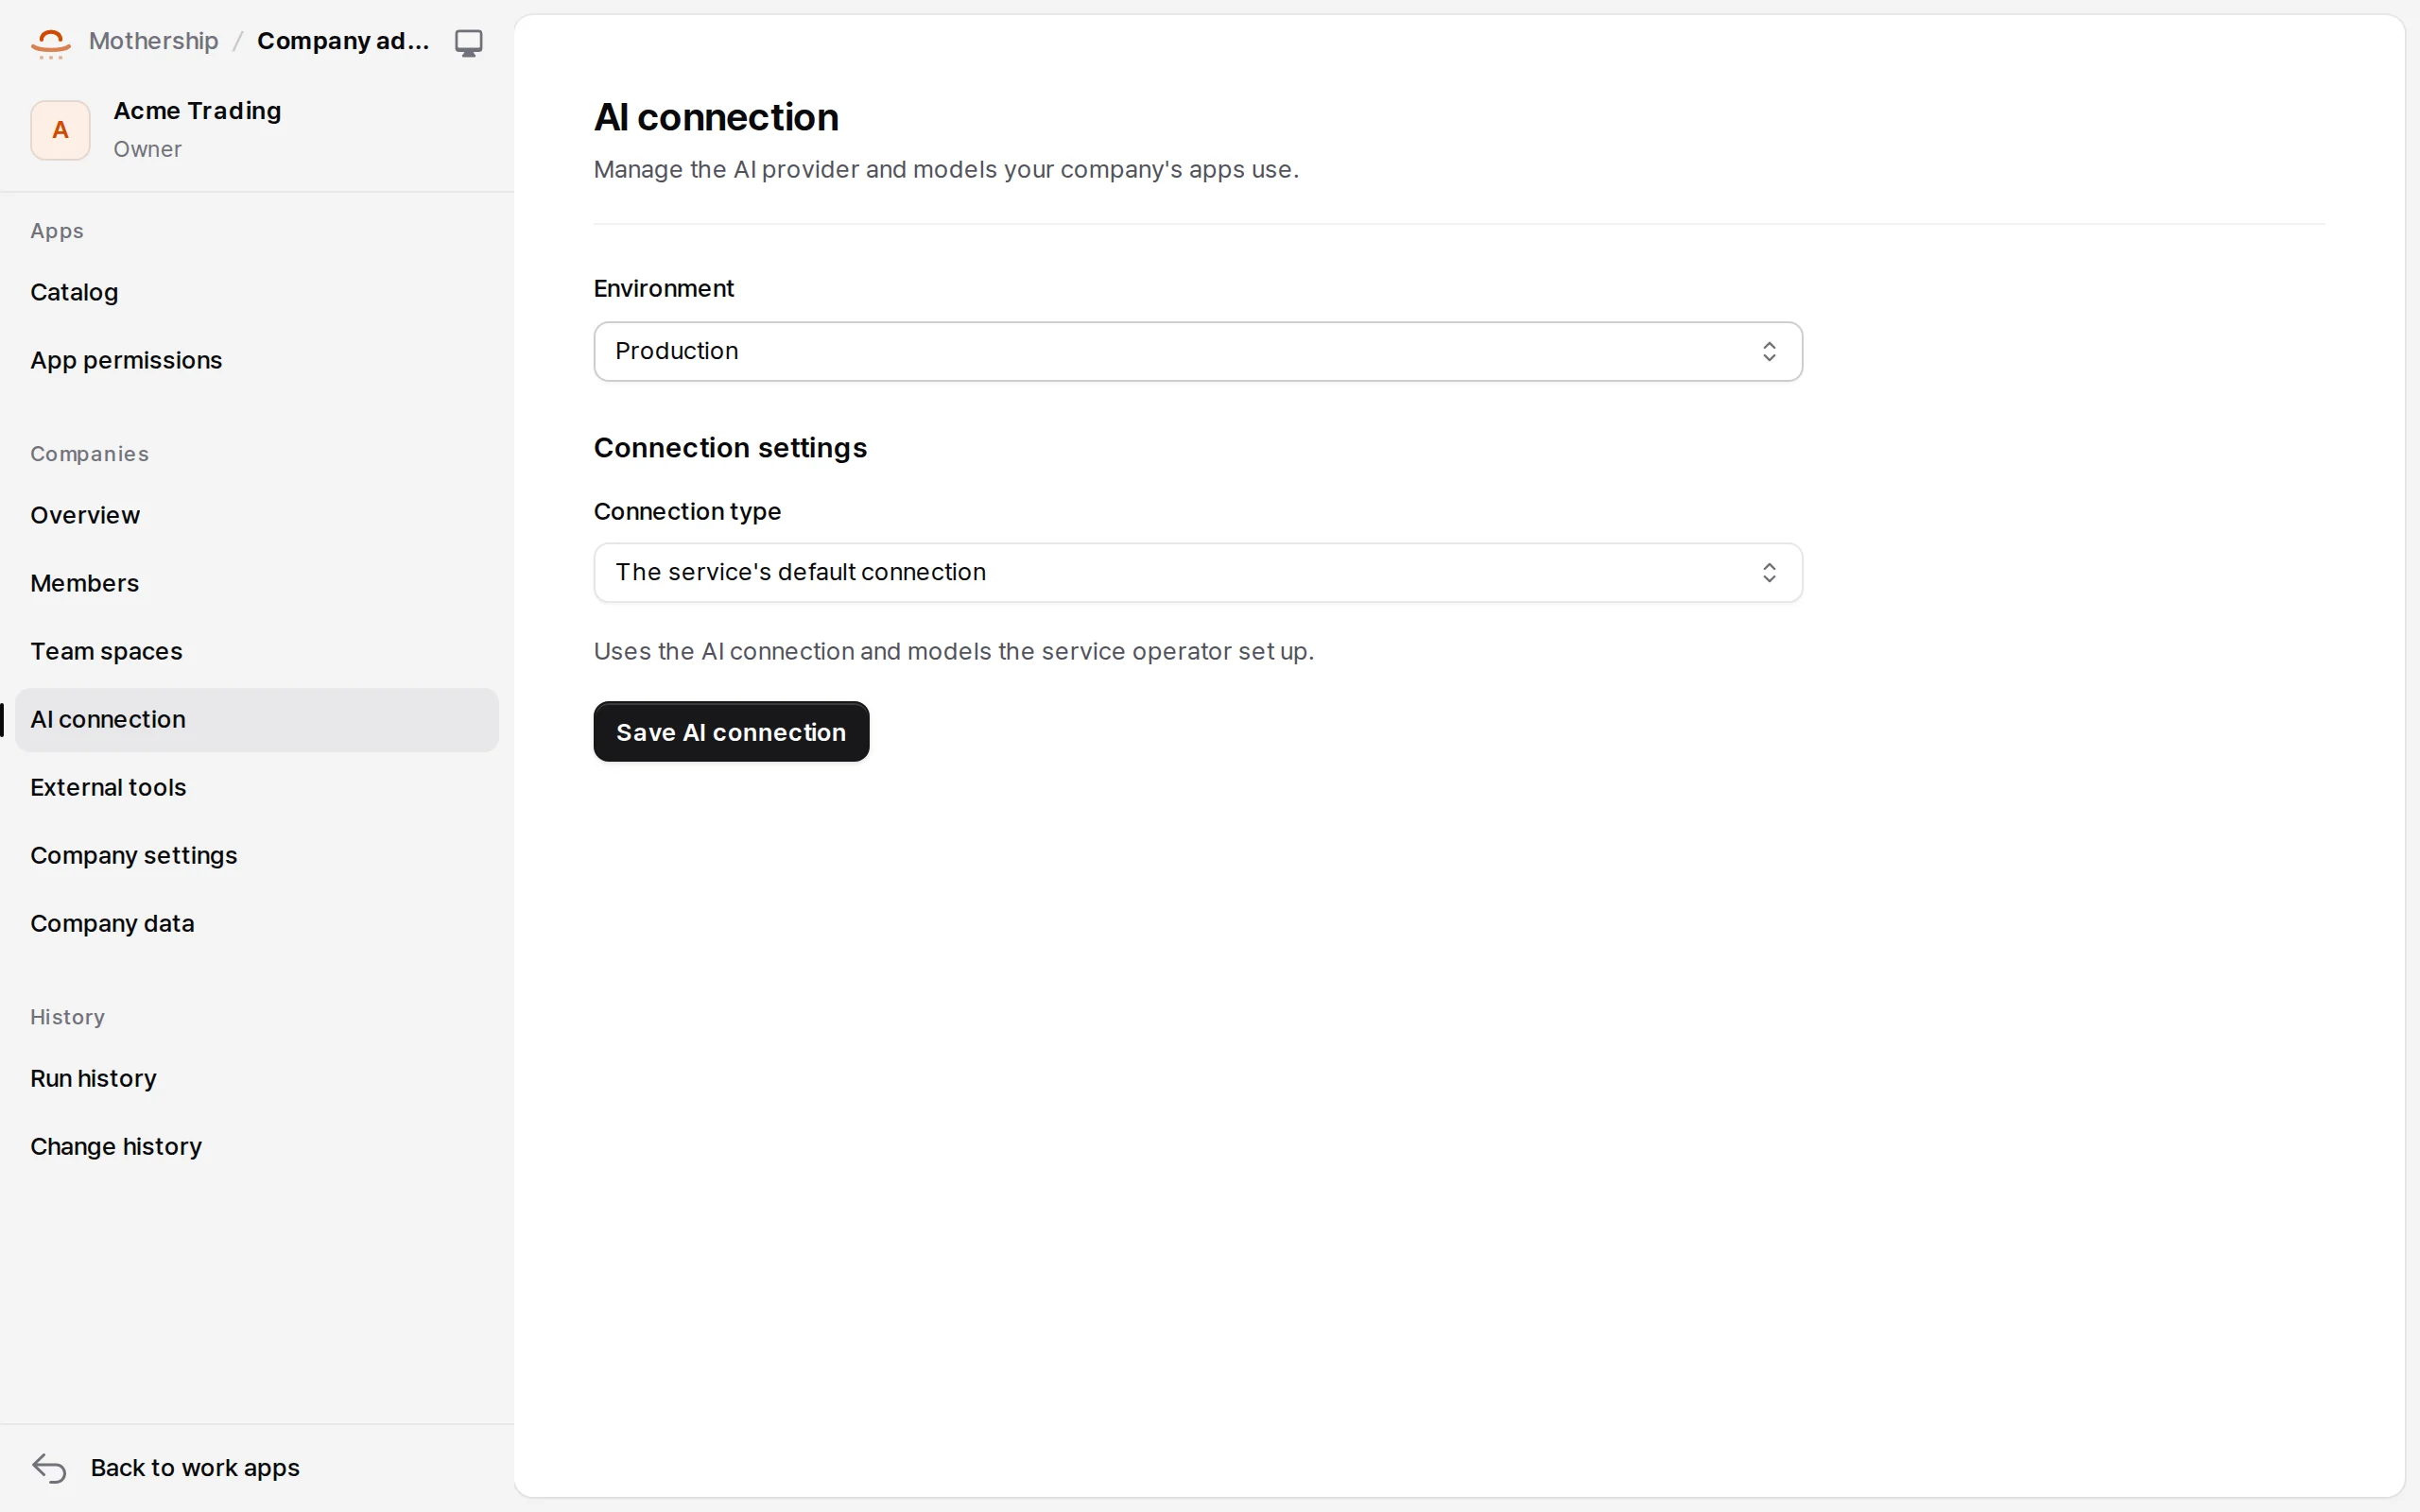
A company administrator can replace the service's provider in Company admin → AI connection with the company's own OpenAI-compatible provider. Only origins the operator approved work (MOTHERSHIP_TENANT_AI_ALLOWED_ORIGINS, default https://api.openai.com). The key is stored encrypted and never shown again. Shared validation and preview don't borrow the company's production key; set them per environment or use the platform default.
Calling it from an app
const reply = await ctx.api.ai.generate({ profile: "smart", messages: [{ role: "user", content: "Summarize this" }] });
for await (const ev of ctx.api.ai.stream({ profile: "fast", messages })) { /* response.delta … */ }
const embedded = await ctx.api.ai.embeddings({ input: ["a sentence"] });   // profile defaults to embedding-default
responseSchemamaps to the provider'sjson_schemaresponse format.attachments(file handles, stored objects) are extracted to text on the server (UTF-8, .docx, .pptx, PDF, OCR'd images) and appended as untrusted documents.- Streams run on the gateway's event loop; an open stream costs a connection, not a thread.
Usage and billing
- Service admin → Overview shows the last 30 days of AI requests and tokens per app, company and person. Prompts, answers and credentials are not stored in the usage ledger.
- Optional billing (
MOTHERSHIP_BILLING_ENABLED=true) adds model prices (microdollars per million tokens), prepaid credits, monthly request and token quotas, per-person and per-app limits and concurrency. Over quota is 429, out of credit 402. Payments (Stripe) are not part of this release.